Snakemake
Perform a quality check on raw sequencing data with Snakemake and Conda
Section titled “Perform a quality check on raw sequencing data with Snakemake and Conda”Overview
Section titled “Overview”Duration: 4
This tutorial is based on a training session conducted by Stéphanie Le Gras from the IGBMC Genomeast platform : http://genomeast.igbmc.fr/wiki/doku.php?id=training:dudijon:qualitycontrol
The purpose of this tutorial is to describe the implementation of a quality check process for raw sequencing data in order to introduce you to the use of Snakemake and Conda on a HPC cluster.
This tutorial has been tested on the IFB Core Cluster however it should work on most infrastructures.
The following diagram describes the process we want to write to perform quality control of our raw sequencing data:
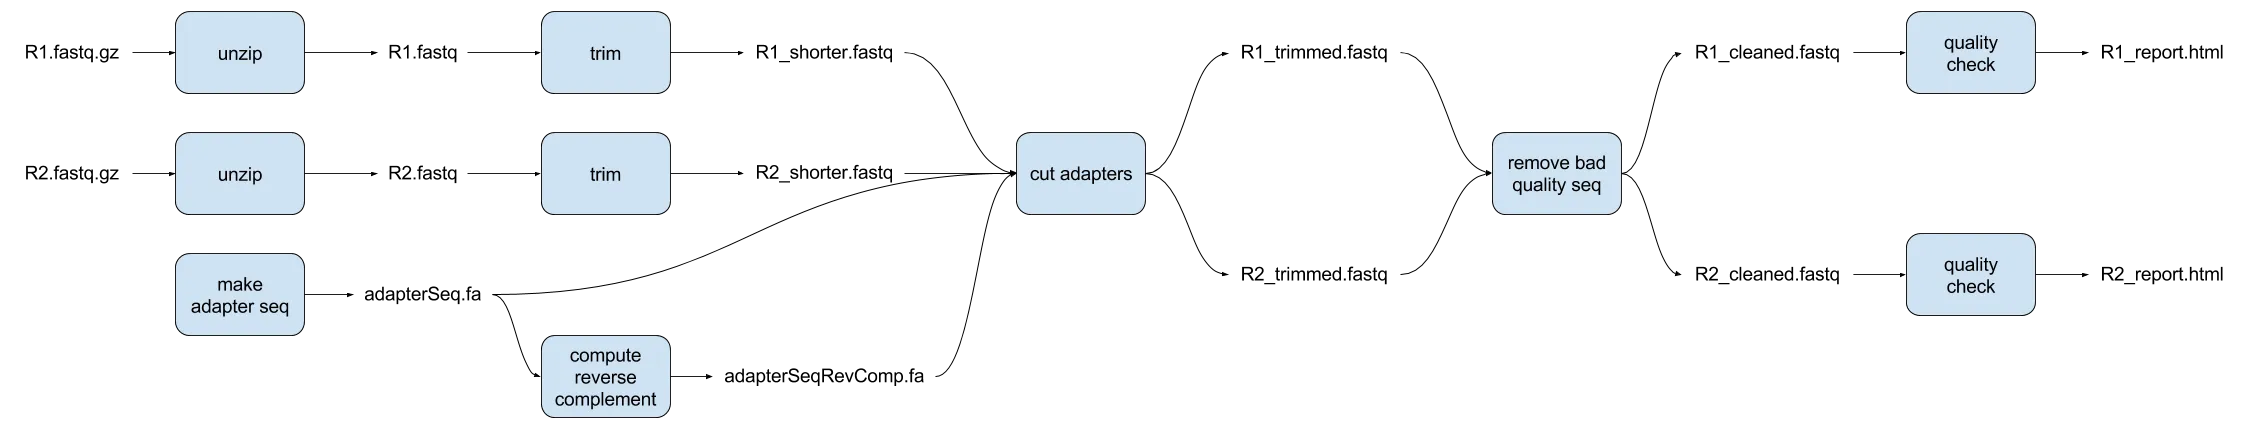
This process is based on two sequence files that correspond to the two ends of the sequenced DNA fragments.
It uses the following tools:
- The
fastxsuite: this suite offers several data processing tools infastqformat cutadapt: this tool allows you to cut the sequences of adapters contained in the readings (cut adapters)SolexaQA++: this tool allows you to reduce a sequence to keep the longest continuous sequence with the best quality.fastqc: this tool allows you to generate a sequencing data quality report
During this tutorial we will develop the steps of this process using snakemake. We will also use conda to install the necessary tools. Finally, we will launch this process on a HPC cluster to analyze test data.
About work environment and test data
Section titled “About work environment and test data”Duration: 4
The process we want to perform will generate some intermediate files that we do not necessarily want to keep. In order to better organize our data processing, we will choose which files we want to keep and how we will organize the storage of these files.
The input data (compressed FASTQ files) will be stored in a data folder in our current directory.
In order to easily identify the pairs of sequences to be processed, we will use the following naming rule:
data/<sample_identifier>-R1.fastq.gz: end 1 of the sample to be analyseddata/<sample_identifier>-R2.fastq.gz: end 2 of the sample to be analysed
The intermediate files will be stored in a tmp folder in our current directory.
Finally, the result files will be stored in a result folder.
When our processing is completed we want to keep the two sequences of each sample in FASTQ format as well as the quality check report of each sequence in HTML format.
We will then have the following files:
result/<sample_identifier>-R1.fastq: cleaned sequence of the end 1 of the sample to be analysedresult/<sample_identifier>-R1-fastqc.html: quality check report of end 1 of the sample to be analysedresult/<sample_identifier>-R2.fastq: cleaned sequence of the end 2 of the sample to be analysedresult/<sample_identifier>-R2-fastqc.html: quality check report of end 2 of the sample to be analysed
Download the test data
Section titled “Download the test data”Duration: 5
Create a tutorial folder in your home directory
Section titled “Create a tutorial folder in your home directory”mkdir tutorialcd tutorialDownload the test data for the tutorial using the wget command”
Section titled “Download the test data for the tutorial using the wget command””mkdir datasrun wget -P data https://gitlab.com/ifb-elixirfr/cluster/qc-with-snakemake-and-conda/raw/master/data/CRN-107_11-R1.fastq.gzsrun wget -P data https://gitlab.com/ifb-elixirfr/cluster/qc-with-snakemake-and-conda/raw/master/data/CRN-107_11-R2.fastq.gzGet Snakemake
Section titled “Get Snakemake”Duration: 5
To carry out our process we will rely on Snakemake (https://snakemake.readthedocs.io) which is a workflow management system.
Snakemake allows you to control the execution of a defined data processing based on a series of transformation rules that constitute the processing steps. Once the transformation rules are defined, Snakemake is able to automatically determine the process to be followed to obtain a result (e.g. a quality check report) from the data available.
The snakemake command is usually invoked, indicating the results you want to obtain.
In our case, once the rules of our processing have been established, we will be able to invoke snakemake as follows:
snakemake result/CRN-107_11-R1-fastqc.html result/CRN-101_11-R2-fastqc.htmlWe will come back later on the execution of this command in this tutorial.
Benefits of using Snakemake: : There are many workflow management systems. We chose Snakemake because it is widely used by the bioinformatics community and interfaces very easily with a calculation farm and the Conda package deployment tool.
There are several ways to get snakemake in our work environment :
Use module
Section titled “Use module”Snakemake is maybe already available on your cluster. You can check it by loading it with module.
Load the snakemake module:
module load snakemakeInstall with conda
Section titled “Install with conda”If you can’t find any snakemake module on your cluster, you should be able to install it with conda.
Create conda environment for Snakemake:
conda create -n snakemake-env -c bioconda -c conda-forge snakemakeOnce the conda environment has been created, you just have to activate it each time you want to work with snakemake:
conda activate snakemake-envYou can find other ways to install snakemake in the official documentation. Don’t hesitate to contact your cluster administrator if you can’t find a proper way to make it work in your environment.
When ready, verify that the snakemake program is working:
snakemake --versionThis command should return the version of snakemake available in your environment.
Create a Snakefile
Section titled “Create a Snakefile”Duration: 2
In order to describe the transformation rules that we want to implement in our data processing, we must write a Snakefile.
A Snakefile is a text file with a syntax similar to Python. This syntax makes it possible to describe in a simple way the different processing steps that can result in the execution of shell commands or the execution of Python code. Don’t worry, you don’t need to know Python to use Snakemake !
By default, when you run the snakemake command, it searches for a Snakefile in the current directory. However, it is possible to specify a Snakefile located elsewhere using the --snakefile option.
Your first Snakemake rule : unzip
Section titled “Your first Snakemake rule : unzip”The first step in our processing is to unzip the fastq.gz files using the gunzip command.
If we had to perform this step manually, we would execute the following commands:
gunzip -c data/CRN-107_11-R1.fastq.gz > tmp/CRN-107_11-R1.fastqgunzip -c data/CRN-107_11-R1.fastq.gz > tmp/CRN-107_11-R1.fastqWe will write a first Snakemake rule that will unzip any .fastq.gz file from the data folder to a .fastq file of the same name in the tmp folder.
Create your Snakefile in your current directory and declare the following rule:
rule unzip: input: "data/{sample}.fastq.gz" output: "tmp/{sample}.fastq" shell: "gunzip -c {input} > {output}"What does this code means?
Section titled “What does this code means?”Let’s see in details how this first rule is defined :
rule unzip:The keyword rule allows you to declare a new rule with the name unzip.
input: "data/{sample}.fastq.gz"The input section is used to declare the rule’s input files.
The wildcard {sample} is used to designate the variable part in the name of the input files (in this case the sample identifier).
Indeed, our workflow is designed to work with any pair of sequences, so we need to indicate to Snakemake the naming convention we chose and which part of the filename is considered variable.
output: "tmp/{sample}.fastq"The output section describes the output files of the rule.
The wildcard {sample} is used again to name the output file according to the name of the input file.
shell: "gunzip -c {input} > {output}"The shell section allows you to declare one or more commands that will be executed for this rule.
The keywords {input} and {output} are used to refer to the input and output files of the rule.
Deleting temporary files
Section titled “Deleting temporary files”We want the files generated in the tmp folder to be automatically deleted by Snakemake as soon as they are no longer needed.
The temp() instruction allows you to tell Snakemake about temporary files.
Use the temp() instruction to tell Snakemake to automatically delete the .fastq files at the end of processing:
rule unzip: input: "data/{sample}.fastq.gz" output: temp("tmp/{sample}.fastq") shell: "gunzip -c {input} > {output}"Creating the tmp folder
Section titled “Creating the tmp folder”When the workflow is started for the first time, it is possible that the tmp folder we want to use does not yet exist.
Modify your unzip rule to create the tmp folder if it doesn’t already exist:
rule unzip: input: "data/{sample}.fastq.gz" output: temp("tmp/{sample}.fastq") shell: """ mkdir -p tmp gunzip -c {input} > {output} """Launch Snakemake
Section titled “Launch Snakemake”Duration: 5
Snakemake automatically picks up the Snakefile file located in the current directory to retrieve rules.
To let Snakemake execute our first rule, we will ask it to generate the uncompressed sequence files.
Note that we need to pass to Snakemake the result files we would like to generate.
srun snakemake --jobs=1 tmp/CRN-107_11-R1.fastq tmp/CRN-107_11-R2.fastqDrawback of this method:
: For now we are using srun to start snakemake in order to run our workflow on compute resources. At the end of the tutorial we will learn how to make snakemake start each rule as a separate cluster job in order to have better control over each step execution.
When Snakemake starts, it determines the sequence of rules to execute to obtain the desired result by building a directed acyclic graph (DAG) which constitutes the dependencies tree of the files to be generated. The DAG will also help Snakemake to determine which rules can be run in parallel.
Building DAG of jobs...Using shell: /usr/bin/bashProvided cores: 1Rules claiming more threads will be scaled down.Job counts: count jobs 2 unzip 2At this point snakemake tells us that 2 unzip jobs need to be run (one for each sequence file expected).
Snakemake then starts each job. By default, it can work on only one job at a time so all jobs are running sequentially. We can follow the execution of each job in real time.
[Thu Nov 14 13:32:18 2019]rule unzip:    input: data/CRN-107_11-R2.fastq.gz    output: tmp/CRN-107_11-R2.fastq    jobid: 1    wildcards: sample=CRN-107_11-R2
[Thu Nov 14 13:32:19 2019]Finished job 1.1 of 2 steps (50%) done
[Thu Nov 14 13:32:19 2019]rule unzip:    input: data/CRN-107_11-R1.fastq.gz    output: tmp/CRN-107_11-R1.fastq    jobid: 0    wildcards: sample=CRN-107_11-R1
[Thu Nov 14 13:32:20 2019]Finished job 0.2 of 2 steps (100%) done
For each job we can see what input files have been chosen and which output files will be generated. We can also view the wildcards variables generated during the workflow.
The trim rule
Section titled “The trim rule”Duration: 5
The next step is to reduce the sequences to recover only the last nucleotides for each fastq file. To do this, we will use the fastx_trimmer command from the fastx tools collection.
Here is an example of using the fastx_trimmer command for one of the files used in this tutorial:
fastx_trimmer -f 1 -l 100 -Q 33 -i tmp/CRN-107_11-R1.fastq -o tmp/CRN-107_11-R1_shorter.fastqWrite the trim rule that reduces the fastq files in the tmp folder
Section titled “Write the trim rule that reduces the fastq files in the tmp folder”rule trim: input: "tmp/{sample}.fastq" output: temp("tmp/{sample}_shorter.fastq") shell: "fastx_trimmer -f 1 -l 100 -Q 33 -i {input} -o {output}"Start Snakemake processing to generate the reduced fastq files
Section titled “Start Snakemake processing to generate the reduced fastq files”srun snakemake --jobs=1 tmp/CRN-107_11-R1_shorter.fastq tmp/CRN-107_11-R2_shorter.fastqBy running this command, Snakemake tells us that it is failing to execute the trim rule.
The output specifies that it can’t find the command fastx_trimmer.
Install dependencies with conda
Section titled “Install dependencies with conda”The fastx_trimmer tool is required to perform the trim step of our process. However, this tool is not available by default on our system.
We could choose to load it using module environments provided on our cluster, however in order to make sure that our workflow will reproducible, we choose to ask snakemake to install it.
We will use the conda package system to control the automatic installation of this tool and ensure that the correct version of the tool is used.
For each rule Snakemake supports a conda parameter that indicates the path to a description file of a conda environment.
We will create an env.yaml file for our workflow that will define the conda environment that will have to be set up to execute our different rules. This will allow us to feed this file whenever we need to install an additional tool.
More about conda: : To learn more about conda, follow our online documentation.
The fastx_trimmer tool is provided by the fastx_toolkit package of the bioconda channel.
Create a env.yaml file that describes a conda environment that has the fastx_toolkit package in version 0.0.14”
Section titled “Create a env.yaml file that describes a conda environment that has the fastx_toolkit package in version 0.0.14””channels: - bioconda - conda-forge - defaultdependencies: - fastx_toolkit==0.0.14Modify your Snakemake to refer to your conda environment for the trim rule
Section titled “Modify your Snakemake to refer to your conda environment for the trim rule”rule trim: input: "tmp/{sample}.fastq" output: temp("tmp/{sample}_shorter.fastq") conda: "env.yaml" shell: "fastx_trimmer -f 1 -l 100 -Q 30 -i {input} -o {output}"To let snakemake install our dependencies through conda, we need to make sure that the conda utility is available in our path.
On most cluster, you will just have to load its module:
module load condaIf conda is not available, you might be able to install it in your homedir following the miniconda documentation.
Restart Snakemake so that it generates the reduced fastq files based on your conda environment
Section titled “Restart Snakemake so that it generates the reduced fastq files based on your conda environment”srun snakemake --jobs=1 --use-conda tmp/CRN-107_11-R1_shorter.fastq tmp/CRN-107_11-R2_shorter.fastqDon’t forget the --use-conda option to instruct snakemake to take care of installing your dependencies with conda
This time the trim rule runs correctly for both fastq files. Note that the unzip rule is not re-run because the unzipped files have already been generated during a previous launch of Snakemake. After the execution of the trim rule, the input fastq files are deleted because they are no longer useful for the analysis.
Use a configuration file
Section titled “Use a configuration file”Duration: 5
The fastx_trimmer command we just used takes a fastq file as input and generates a shorter fastq file according to the specified parameters. Among these parameters we specify the encoding quality corresponding to our input files (-Q 33). This parameter must be modified easily when using our workflow.
Snakemake supports configuration parameters that are accessible through the {config} variable when defining rules.
The parameters can be passed to snakemake directly on the command line:
snakemake --config my_param=1.5Or by means of a file in JSON or YAML format:
snakemake --configfile config.yamlIt is also possible to declare a default configuration file that will contain the default settings that we want to apply to our processing. This file is declared in the Snakefile by means of the keyword configfile.
configfile: "config.yaml"For our processing, we will create the file config.yaml which will contain the default settings.
Create a config.yaml file that contains the encoding_quality parameter
Section titled “Create a config.yaml file that contains the encoding_quality parameter”encoding_quality: 33Use the default configuration file in your Snakefile to set the trim rule
Section titled “Use the default configuration file in your Snakefile to set the trim rule”configfile: "config.yaml"
rule unzip: input: "data/{sample}.fastq.gz" output: temp("tmp/{sample}.fastq") shell: """ mkdir -p tmp gunzip -c {input} > {output} """
rule trim: input: "tmp/{sample}.fastq" output: temp("tmp/{sample}_shorter.fastq") conda: "env.yaml" shell: "fastx_trimmer -f 1 -l 100 -Q {config[encoding_quality]} -i {input} -o {output}"For more information about configuration in Snakemake, see the official documentation.
Generate adapters sequences
Section titled “Generate adapters sequences”Duration: 8
The next step in our treatment consists in cutting the adapters from our sequences, however before this step, we must prepare the sequence of the adapter and generate its reverse complement sequence.
We need to generate two sequence files for the adapters:
- adapterSeq.fa: the sequence of the adapter
- adapterSeqRevComp.fa: the reverse complement sequence of the adapter
Two commands will be used for this purpose:
echo -e ">illumina_adapter_forward\nAGATCGGAAGAGC" > tmp/adapterSeq.faand
fastx_reverse_complement -i tmp/adapterSeq.fa -o tmp/adapterSeqRevComp.faLet’s write the two rules for generating the adapter sequence file and the reverse complement sequence file.
Negative:
: It must be possible to pass the sequence of the adapter as a parameter to Snakemake.
The default adapter sequence is: AGATCGGAAGAGC
Add the make_adapter_seq rule to the Snakefile file
Section titled “Add the make_adapter_seq rule to the Snakefile file”rule make_adapter_seq: output: temp("tmp/adapterSeq.fa") shell: """ echo -e ">illumina_adapter_forward\n{config[adapter_seq]}" > tmp/adapterSeq.fa """The make_adapter_seq rule does not take an input file since it generates a file from a sequence. The adapter sequence is retrieved from the processing configuration through the adapter_seq parameter.
As for each intermediate step of our processing, the output file is marked as temporary using the temp() instruction.
Add the compute_reverse_complement rule to the Snakefile file
Section titled “Add the compute_reverse_complement rule to the Snakefile file”rule compute_reverse_complement: input: "tmp/adapterSeq.fa" output: temp("tmp/adapterSeqRevComp.fa") conda: "env.yaml" shell: "fastx_reverse_complement -i {input} -o {output}"The reverse complement sequence is generated from the sequence generated by the previous rule. The fastx_reverse_complement tool is included in the bioconda fastx_toolkit package, so we indicate that we want to use our conda env.yaml environment to execute this rule.
The output file is marked as temporary using the temp() instruction.
Declare the default value for the parameter adapter_seq in the file config.yaml
Section titled “Declare the default value for the parameter adapter_seq in the file config.yaml”encoding_quality: 33adapter_seq: AGATCGGAAGAGCRemove adapters: a rule with multiple entries
Section titled “Remove adapters: a rule with multiple entries”Duration: 5
The next step in our workflow is to remove the adapters contained in our readings using the cutadapt tool.
The cutadapt tool takes many input and output parameters. Here is an example of using the cutadapt command for the files used in this tutorial:
cutadapt -a AGATCGGAAGAGC -A $(tail -n1 tmp/adapterSeqRevComp.fa) -o tmp/CRN-107_11-R1_trimmed.fastq -p tmp/CRN-107_11-R2_trimmed.fastq tmp/CRN-107_11-R1_shorter.fastq tmp/CRN-107_11-R2_trimmed.fastqDescribe this new rule and identify precisely the input files as well as the output files by assigning them identifiers
Section titled “Describe this new rule and identify precisely the input files as well as the output files by assigning them identifiers”rule cut_adapters: input: adapter_reserve_complement = "tmp/adapterSeqRevComp.fa", r1 = "tmp/{sample}-R1_shorter.fastq", r2 = "tmp/{sample}-R2_shorter.fastq" output: r1 = temp("tmp/{sample}-R1_trimmed.fastq"), r2 = temp("tmp/{sample}-R2_trimmed.fastq") conda: "env.yaml" shell: "cutadapt -a {config[adapter_seq]} -A $(tail -n1 {input.adapter_reserve_complement}) -o {output.r1} -p {output.r2} {input.r1} {input.r2}"In order to retrieve the adapter sequence more easily, we use the value contained in the configuration, rather than the file used to calculate the reverse complement.
Before we can perform this new step, we must add the cutadapt tool in our conda environment.
Edit the env.yaml file of our process
Section titled “Edit the env.yaml file of our process”channels: - biocondadependencies: - fastx_toolkit==0.0.14 - cutadapt==1.12Clean sequences
Section titled “Clean sequences”Duration: 8
Before we can generate our quality report, there is one last step left to do on our sequences; reduce them to keep the longest continuous sequence with the best quality. To do this we use the tool SolexaQA++.
Here is an example of using the command SolexaQA++:
SolexaQA++ dynamictrim -h 10 -d tmp tmp/CRN-107_11-R1_trimmed.fastq tmp/CRN-107_11-R2_trimmed.fastqA particularity of this tool is that it generates a large number of output files without being able to finely control their naming. However, we are only interested in the two cleaned sequence files, so we must tell Snakemake that we do not want to keep the other outputs.
Write the rule remove_bad_quality_seq
Section titled “Write the rule remove_bad_quality_seq”This rule will clean the files .trimmed.fastq contained in the tmp folder in order to get only the output of the cleaned fastq files in the result folder
The rule will have to take as parameter the desired quality score which will have the default value 10.
This is the new rule we need to add to our Snakefile file:
rule remove_bad_quality_seq: input: r1 = "tmp/{sample}-R1_trimmed.fastq", r2 = "tmp/{sample}-R2_trimmed.fastq" output: r1 = "result/{sample}_R1.fastq", r2 = "result/{sample}_R2.fastq", r1_segments = temp("tmp/{sample}-R1_trimmed.fastq_trimmed.segments"), r2_segments = temp("tmp/{sample}-R2_trimmed.fastq_trimmed.segments"), conda: "env.yaml" shell: """ SolexaQA++ dynamictrim -h {config[phred_quality_score]} -d tmp {input.r1} {input.r2} mkdir -p result mv {input.r1}.trimmed {output.r1} mv {input.r2}.trimmed {output.r2} """All unnecessary outputs are declared temporary using the temp() command in order to be automatically deleted by Snakemake. The cleaned sequence files are automatically named with a .trimmed extension by SolexaQA++. So we move these files to the result folder and rename them at the same time.
Declare the default value of the parameter phred_quality_score in the file config.yaml
Section titled “Declare the default value of the parameter phred_quality_score in the file config.yaml”encoding_quality: 33adapter_seq: AGATCGGAAGAGCphred_quality_score: 10Add the solexaqa package in the conda environment”
Section titled “Add the solexaqa package in the conda environment””channels: - biocondadependencies: - fastx_toolkit==0.0.14 - cutadapt==1.12 - solexaqa==3.1.7.1Quality check
Section titled “Quality check”Duration: 5
The last step of our workflow is to generate the quality report using the fastqc tool.
Here is an example of using the fastqc command:
fastqc --nogroup result/CRN-107_11_R1.fastqWrite a rule to generate a quality report for each sequence
Section titled “Write a rule to generate a quality report for each sequence”rule fastqc: input: r1 = "result/{sample}_R1.fastq", r2 = "result/{sample}_R2.fastq" output: "result/{sample}_R1_fastqc.html", "result/{sample}_R2_fastqc.html", "result/{sample}_R1_fastqc.zip", "result/{sample}_R2_fastqc.zip" conda: "env.yaml" shell: """ fastqc --nogroup {input.r1} fastqc --nogroup {input.r2} """We want to keep all fastqc outputs as the final result.
Launch the workflow on a cluster
Section titled “Launch the workflow on a cluster”For testing purposes, we have been running snakemake inside a unique srun job from the login node of the cluster. This means that all rules are running inside the same SLURM job and can’t run in parallel. In order to make our workflow more efficient, we want Snakemake to run each rule of our workflow in a separate cluster job. Snakemake supports different ways to interact with a cluster. The method supported by most cluster queueing systems is DRMAA (Distributed Resource Management Application API).
In order to enable the DRMAA support, we must first make sure that the environment variable DRMAA_LIBRARY_PATH is pointing to the DRMAA library of our cluster.
Benefit of using the IFB Core cluster:
: On the IFB cluster, you just have to load the slurm-drmaa module to enable the DRMAA support.
module load slurm-drmaaecho $DRMAA_LIBRARY_PATHIf the DRMAA_LIBRARY_PATH is not set on your cluster and you can’t find a module to load drmaa support, you may ask your cluster administrators for help.
Run the full workflow on the cluster:
snakemake --drmaa --jobs=10 result/CRN-107_11-R1.html result/CRN-107_11-R2.htmlWe pass two options to snakemake :
--drmaa: tells snakemake that we want to run jobs through DRMAA--jobs: tells snakemake the max number of jobs we want to run in parallel. This parameter is mandatory when we use the--drmaaoption. It should be at least 1.
When snakemake is running, we can follow each job it is submitting to the cluster. For instance :
Submitted DRMAA job 0 with external jobid 3152659The external jobid will help us to retrieve the job output. Indeed, for each job, SLURM creates an output file in the format slurm-xxxx.out where xxxx is the SLURM job id. This file can give you interesting information when a job is failing.